Что такое концепция Digital-First, и на что она влияет
Цифровые технологии с фантастической скоростью меняют концепцию ведения бизнеса. Компаниям, стремящимся опередить конкурентов и развиваться в цифровом мире, не обойтись без цифровых технологий. Стратегия Digital-First – это широкий и разнообразный подход к развитию бизнеса, включающий использование цифровых элементов.
Стратегия Digital-First предлагает совершенно новый подход, ориентированный на цифровые технологии. Он должен стать стандартом в любой бизнес-среде.
Концепция Digital-First включает в себя следующие методы:
· развитие брендинга для повышения узнаваемости, увеличения конверсии;
· расширение рабочего диапазона с помощью цифровых методов определения геопозиции;
· усиление безопасности для защиты данных компании и клиентов;
· улучшение доступа к информации для потенциальных клиентов и сотрудников;
· анализ деятельности сотрудников компании с помощью цифровых инструментов для оценки влияния их работы на прибыль;
· повышение конкурентоспособности при помощи оптимизации маркетинга.
Такая стратегия помогает вывести бизнес на новый уровень, повысить конверсии и прибыль.
Цифровой подход все чаще используется в современном маркетинге и в брендинге, вытесняя традиционные маркетинговые тактики. Для успешного ведения бизнеса компаниям необходимо уделять особое внимание digital-технологиям. Благодаря им бренд становится видимым и узнаваемым в сети. Если бренд не имеет достаточной узнаваемости при поиске в интернете, он упускает возможность взаимодействия с аудиторией.
Существуют экономически выгодные способы digital-маркетинга, в которые входят:
· поисковая оптимизация SEO, которая способна сделать веб-ресурс компании более заметным в поисковой системе;
· продвижение в социальных сетях, с помощью которых бизнес получает возможность взаимодействия с миллионами пользователей;
· рассылка рекламных уведомлений о товарах и услугах через почтовые сервисы;
· платная реклама в поисковых системах и на спонсируемых сайтах;
· платная система Pay Per Click для увеличения просмотров предлагаемого товара или услуги.
Элемент, который остается в памяти пользователя как визитная карточка компании – это логотип. Он должен одинаково эффективно работать на любой платформе и устройстве.
Многие компании начинали свою деятельность еще до внедрения цифровых технологий в таких масштабах, как сегодня, поэтому их логотип представляет собой изображение, содержащее мелкие детали. Для использования лого на веб-странице требуется его упрощенная версия, которая не содержит мелких элементов и надписей.
Идеальным вариантом упрощенной версии логотипа может стать фирменный знак, разработанный без потери узнаваемости бренда. Знак должен эффектно смотреться как на большом экране компьютера, так и на мобильном устройстве.
Стратегия Digital-First включает в себя методы, которые сосредоточены на высоком качестве контента, публикуемого в социальных сетях и на веб-ресурсах компании. С помощью контента можно улучшить взаимодействие с аудиторией, увеличить ее численность.
Для того, чтобы контент был качественным, необходимо придерживаться некоторых правил:
· четко знать свою целевую аудиторию;
· придерживаться определенной темы, отвечающей потребностям целевой аудитории;
· создавать уникальный материал, доступный для чтения и восприятия;
· уделять внимание качеству визуального контента и оформления;
· избегать опечаток и орфографических ошибок;
· публиковать только достоверную информацию;
· постоянно обновлять публикации.
Для повышения лояльности целевой аудитории обязательным условием является обратная связь. Можно проводить опросы в блоге и в социальных сетях. При этом необходимо брать во внимание мнение каждого клиента, отвечать на его вопросы.
Стратегия Digital-First предусматривает использование цифровых инструментов для оказания помощи и поддержки потенциальных клиентов. Одним из инструментов коммуникации служит онлайн-чат. С его помощью клиенты могут взаимодействовать с менеджерами компании на сайте в режиме реального времени. Разместить чат на странице сайта можно с помощью специальных сервисов.
Формат Digital-First автоматизирует рутинные операции, позволяя сотрудникам заняться наиболее важными видами работы. Рабочее пространство, созданное в цифровом формате, помогает сотрудникам анализировать статус текущего проекта, собирать аналитические данные. Цифровые инструменты делают возможным обсуждение бизнес-задач и их согласование с коллегами.
Цифровые инструменты помогают создать гибкий рабочий график, нацеленный на максимальную продуктивность. С помощью инструментов можно оценивать работу сотрудников не по действиям, а по полученным результатам.
Правильная организация цифрового рабочего места адаптирует рабочую среду под задачи сотрудников. Единая платформа для работы способствует систематизации данных, улучшению и персонализации контента, стимулирует продуктивность, помогает в привлечении кадров и их удержании.
В основу цифрового рабочего процесса входят такие функции:
· совместная работа с документами;
· групповые чаты, видео конференции;
· онлайн-календарь, планировщики задач;
· доступ к профилям всех сотрудников, создание рейтингов.
Поддерживать эти функции можно с помощью таких корпоративных приложений:
Data First — the New Scientific Method?
Does the basic foundation of elementary science education hold up in the world of big data?

One of the challenges to research and analytics today is an extreme shift in methodology and sequence due to the explosion of “Big Data.” The raw information in big data sets and streams is continually updating and growing based on automated output from systems and sensors. However, the basic reality remains that most problems–and most data sets–usually only deal with small to medium data. The data may exist beforehand or be generated using traditional methods of gathering and experimentation. The fact remains that there is an enormous volumetric difference between traditional data sets and raw “Big” data sets.
One of the advantages of the traditional methods of data gathering is that the data is often predetermined by the research methodology (survey, study, etc). While there are challenges to that approach, even the raw data itself is often quite reliable as it is validated at many stages. Big data is generally just “raw.” However, we also need to look at the value of the data. The value of traditional data might be seen to increase once it is collected and validated. Since it was gathered/generated for a specific use it holds its value consistently, but it does not increase until the next round of experimentation or collecting. Big data is continuously growing. Even in its most unrefined form there is potential value growth based on its volume and history. Let’s take something like sales data for example. If you are tracking all transactions over time, there is inherent value to that data set as it grows. If you then augment the data with information about product categories or user demographics for purchasers, the entire data set is now much more valuable. Once you analyze and model the augmented dataset you again increase the value and potentially the rate at which it grows in value as the raw data volume increases.
Why you should take a data first approach to AI
Machine learning systems are born through the marriage of both code and data. The code specifies how the machine should learn and the training data encapsulates what should be learned. Academia mostly focuses on ways to improve the learning algorithms, the how of machine learning. When you come to build practical AI systems though, the dataset you're training on has at least as much impact on performance as the choice of algorithm.
Although there are a lot of tools for improving machine learning models, there are very few options when it comes to improving your data set. At Humanloop, we've given a lot of thought to how you can systematically improve data sets for machine learning.
Improving your dataset can dramatically improve AI performance
In a recent talk, Andrew Ng, shared a story from a project he worked on at Landing AI, building a computer vision system to help find defects in steel. Their first attempt at the system had a baseline performance of 76%. Humans could find defects with 90% accuracy so this wasn't good enough to put into production. The team working on the project then split in two. One team worked on trying different model types, hyper-parameters and architecture changes. The other team looked to improve the quality of their data set. After a few weeks of iteration, the results came in. The modeling team despite huge effort had not been able to improve performance at all. The data team on the other hand were able to get a 16% performance improvement. Improving the dataset actually led to super-human performance on this task.
By fixing errors in their data set the data-team was able to take their algorithm from worse than human to super-human.
This story isn't at all unique. I've had a similar experience at Humanloop. We worked with a team of lawyers from one of the big-4 accountancy firms to train a document classifier on legal contracts. Similar to finding defects in steel, the task was subtle and required domain expertise. After the first round of labeling and training was complete, the model still wasn't good enough to match Human level performance. Within Humanloop, there's a tool to investigate data points where there is disagreement between the AI model and the human annotators. Using this view the team were able to find around 30 misclassifications in a data set of 1000 documents. Fixing just these 30 mistakes was enough to get the AI system to match human-level performance.
What do "data bugs" look like?
There's a lot of discussion of "data prep" and "data cleaning" but what actually differentiates high quality data from low quality?
Most machine learning systems today are still using supervised learning. That means that the training data consists of (input, output) pairs and we wish the system to be able to take the input and map to the output. For example, the input may be an audio clip and the output could be the transcribed speech. Or the input might be an image of a damaged car and the output could be the locations of all the scratches. At Humanloop we focus on NLP so an example input for us might be a customer service message and the output could be a templated response. Building these training datasets usually requires having humans manually label the inputs for the computer to learn from.
If there's ambiguity in the way data is labeled then the ML model will need much more data to get to high performance. There are a few different ways that data collection and annotation can go wrong:
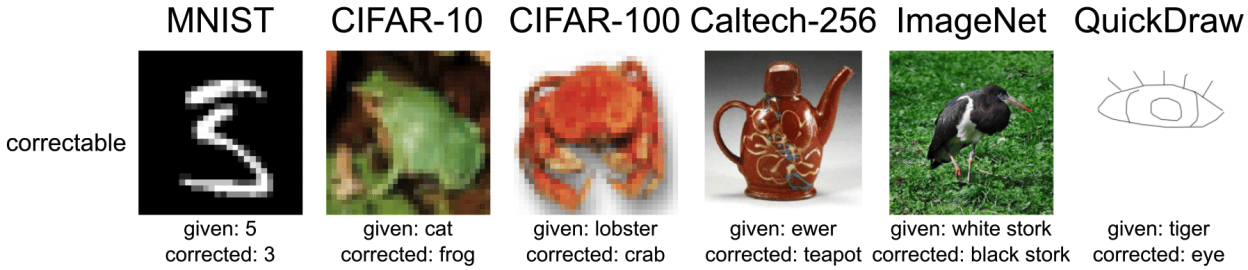
Simple misannotations The simplest type of mistake is just a misannotation. This is when an annotator, perhaps tired from lots of labeling, accidentally puts a data point in the wrong class. Although it's a simple error, it's surprisingly common and can have huge negative impact on AI system performance. A recent investigation of benchmark datasets in computer vision research found that over 3% of all data points were mislabeled. Over 6% of the ImageNet validation data set is mislabeled. How can you expect to get high performance when the benchmark data is wrong?!
Inconsistencies in annotation guidelines There is often subtlety in the correct way to annotate a piece of data. For example, imagine that you are instructed to read social media posts and annotate whether or not they are product reviews. This seems like a straightforward task but once you start annotating you quickly realize that "product" is a remarkably vague instruction. Should you include digital media like podcasts or movies as products? If one annotator says "yes" and another annotator says "no", your AI system will inevitably have lower performance. Similarly if you're asked to put bounding boxes around pedestrians in images for driverless cars, how much of the background should you include?
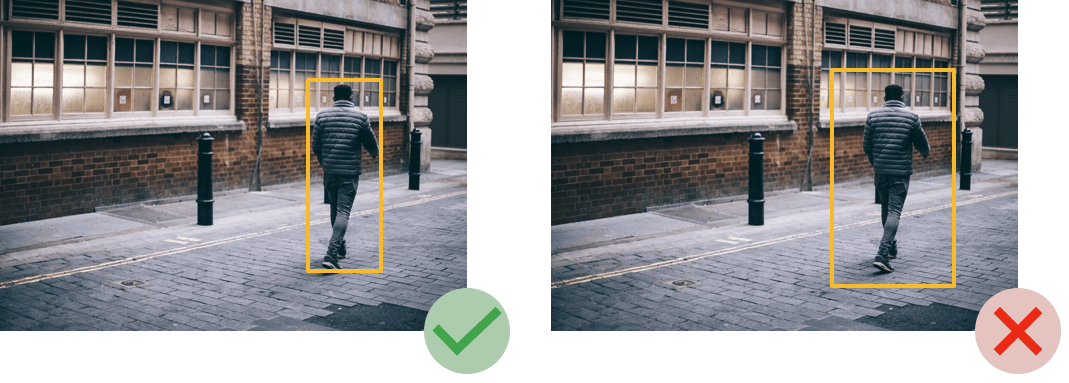
Both of these examples might seem reasonable to a human annotator but if there's inconsistency between annotators then model performance will inevitably suffer. Teams need ways to quickly find sources of confusion between annotators and the model and fix this,
Imbalanced data or missing classes How we collect our data has a big impact on the composition of our datasets and that in turn can affect the performance of models on specific classes or subsets of data. In most real world datasets the number of examples found in each category we want to classify, the class balance, can vary wildly. This can cause worse performance but also exacerbates problems of fairness and bias.
For example, Google AI's face recognition system was famously poor at recognizing people of color and this was in big part a result of having a dataset that didn't have diverse enough examples. (Amongst many other problems)
Tools like active learning help find rare classes in larger datasets and so make it easier to produce rich balanced datasets.
Data quality matters even more in small datasets
Most companies and research groups don't have access to the internet scale datasets that Google, Facebook and other tech giants have. When the dataset is that large you can get away with some noise in your data. However, most teams are operating in domains where they have hundreds to thousands of labeled examples. In this small data regime, data quality becomes even more important.
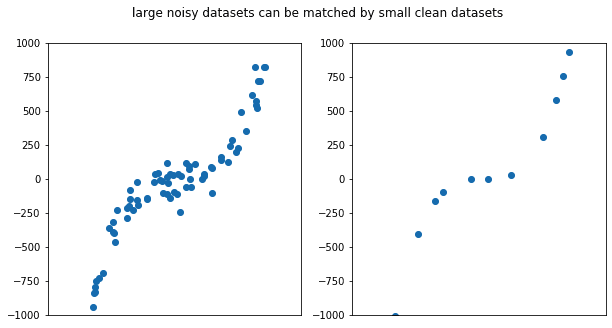
To get some intuition as to why data quality matters so much, consider the very simple 1-dimensional supervised learning problem shown above. In this case we're trying to fit a curve to some measured data points. On the left we see a large noisy dataset and on the right a small clean data set. It's clear that a small number of very low noise data points shows the same curve of a large but noisy dataset. The corollary of this is that noise in small datasets is particularly harmful. Though most machine learning problems are very high dimensional they operate on the same principles as curve fitting and are affected in analogous ways.
Intelligent tooling can make a huge difference to improving data quality
There are lots of tools for improving machine learning models but how can we systematically improve machine learning datasets?
Data Cleaning Tools
A workflow that some teams are beginning to adopt is to iterate between training models and then correcting "data bugs". Tools are emerging to facilitate this workflow such as label noise in context and Aquarium learning or the Humanloop data debugger.
The way these tools work is to use the model being trained to help find "data bugs". This can be done by looking at areas where the model and humans have high disagreement or at classes where there is high disagreement between different annotators. Various different forms of visualization can help find clusters of mistakes and fix them all at once.
Weak Labeling
Another approach to improving datasets is to embrace noise but use heuristic rules to scale annotation.
As we saw in the curve-fitting example above, you can get good results either through very small datasets that are clean or very large datasets that are noisy. The idea behind weak labeling is to automatically generate a very large number of noisy labels. These labels are generated by having subject-matter experts write down heuristic rules.
For example, you may have a rule for an email classifier that says "mark an email as job application if it contains the word 'cv'". This rule will not be very reliable but can be automatically applied to thousands or millions of examples.
If there are lots of different rules then their labels can be combined and denoised to produce high quality data.
Active Learning
Data cleaning tools still rely on humans to manually find the mistakes in data sets and don't help us address the problems of class imbalance described above. Active learning is an approach that trains a model as a team annotates and uses that model to search for high value data. Active learning can automatically improve the balance of data sets and help teams get to high performing models with significantly less data.
Data first approaches lead to better team collaboration
As we've written about recently, one of the big advantages of adopting a data-first approach to machine learning is that it allows for much better collaboration between all the different teams involved. Improving datasets forces collaboration between the subject-matter experts who are annotating data and the data scientists who are thinking about how to train models.
The increased involvement of non-technical subject-matter experts in training and improving machine learning models is one of the most exciting aspects of machine learning software compared to traditional software. At Humanloop we've been working on incorporating machine teaching into the normal workflows of non-technical experts so that they can automate tasks with much less dependence on machine learning engineers. In our next blog, we'll share some of our lessons on how machine learning will be incorporated into many people's daily jobs.
Guide to Digital Transformation: Data-first Architecture

The goal of digital transformation remains the same as ever – to become more data-driven. We have learned how to gain a competitive advantage by capturing business events in data. Events are data snap-shots of complex activity sourced from the web, customer systems, ERP transactions, social media, IoT, streaming, and even from machine-generated data. By collecting and processing event data in real-time, managers gain situational awareness to make better decisions.
Data-driven applications enrich our understanding of business events because they leverage more data. To accomplish this, next generation apps that incorporate machine learning (ML) and artificial intelligence (AI) require schema flexibility and the ability to process very large amounts of data affordably. The goal is to raise the bar on a ‘single version of the truth’ and create advanced processes to improve business outcomes.
Event Data Capture
Event data improves visibility. Enterprise data warehouses that rely on canonical, top-down schemas often fail to describe business events adequately. For example, customer order transactions are sorted and analyzed, but what else do we know about these events? Was the customer referred and by whom? A mobile app, Web or retail customer? What else might the customer want to buy? Event data capture builds context and enables better decisions with more predictable results.
Event data capture may also involve large scale data collection. Structured data from transaction systems provides only a partial picture. Today, up to 80% of enterprise data is unstructured or semi-structured and includes images, email, social media, audio and video. To establish a ‘single version of the truth’ for a particular business event, data collection includes all available data about that event including structured data, files, streaming data, machine logs and raw files.
You might be thinking, “that sounds like a lot of data!” Scalability is usually referred to in simple terms such as how many petabytes can we support. Yet simple bulk scaling to petabytes often results in massive systems that become so big they are less usable. Petabyte file stores become inefficient when you are seeking fine grain results. But when we scale logically to more discrete and specific namespaces, we can describe data better, and processing can be optimized more effectively. Therefore, the scalability challenge has evolved from how many petabytes can we support to how many namespaces can we manage.
Cloud Information Architectures
With so many infrastructure requirements changing, the data-driven enterprise requires a new information architecture to achieve digital transformation. This new information architecture ingests any data, uses object storage to store bulk data at the lowest cost, and scales horizontally on clusters of commodity infrastructure. And of course, the architecture must be real-time since data loses value so fast as it ages.
The rise of multi-cloud, data-first architecture and the broad portfolio of advanced data-driven applications that have arrived as a result require cloud data management systems to collect, manage, govern and build pipelines to channel enterprise data. Cloud Data Architectures span private, multi-cloud and hybrid cloud environments connecting with transaction systems, file servers, the Internet and multi-cloud repositories.
Cloud data platforms are the centerpiece of cloud data management programs, and they manage uniform data collection and data storage at the lowest cost. Archives, data lakes, and content services enable cloud migration projects to connect, ingest, and manage any type of data from any source including legacy systems, mainframes, ERP and even SaaS environments like Salesforce or Workday which have become the new systems of record.
Data migrated to the cloud is often stored “as-is” in buckets to reduce heavy lift ETL processes. The goal is to establish real-time data pipelines to support data-driven applications. When “as-is” data will not meet application requirements, enterprise data lakes are used to cleanse and transform raw data in preparation for future processing. Data preparation provides critical data quality measures including data profiling, data cleansing, data transformation, data enrichment and data modeling.
Data Pipelines and Metadata Management
Data pipelines are a series of data flows where the output of one element is the input of the next one, and so on. Data lakes serve as the collection and access points in a data pipeline and are responsible for access control. As data pipelines emerge across the enterprise, enterprise data lakes become data distribution hubs with centralized controls to federate data across networks of data lakes. Data federation centralizes Metadata Management, Data Governance and compliance control while at the same time enabling decentralized data lake operations.
Metadata Management provides a view of the entire data landscape (including structured, semi-structured, and unstructured data) and helps users understand their data better. Analysts classify, profile and establish consistent descriptions and business context for the data. Metadata Management enables users to explore their data landscape in three ways:
Data lineage helps users understand the data lifecycle including a history of data movement and transformation. Data lineage simplifies root cause analysis by tracing data errors and improves confidence for processing by downstream systems.
Data catalog is a portfolio view of data inventory and data assets. Users browse the data that they need and are able to evaluate data for intended uses.
Business glossary is a list of business terms with their definitions. Data Governance programs require that business concepts for an organization be defined and used consistently.
Cloud Data Management for Compliance
Cloud Data Management also provides consumer data privacy and Data Governance controls that are essential to reduce the risks involved in handling bulk data. Information Lifecycle Management (ILM) manages data throughout its lifecycle and establishes a system of controls and business rules including data retention policies and legal holds. Security and privacy tools like data classification, data masking and sensitive data discovery help achieve compliance with Data Governance policies such as NIST 800-53, PCI, HIPAA, and GDPR. Consumer data privacy and Data Governance are not only essential for legal compliance, they improve data quality as well.
CIOs committed to digital transformation should start with a data-first architecture to successfully interoperate with the cloud and its vast network of data and web services. The goal is to describe business events better using data pipelined from OLTP systems, file stores, databases and mail servers. Whether hosting data lakes, enterprise archives or running NoSQL applications, data-first architecture requires Cloud Data Management to deliver the essential services for successful data-driven applications.